The word makes it sound like a glitch, an occasional trip. That framing is the mistake. For a business putting an LLM in front of customers, employees, or financial decisions, hallucination is not an edge case to laugh off, it is an operational risk with a known rate, known trigger conditions, and a known set of controls, the same way a payment system plans for fraud rather than hoping it will not happen. The rate is measurable, and so is the trade behind it: on one OpenAI evaluation, two models scored near-identical accuracy while one almost never declined to answer and was wrong 75% of the time, against 26% for the one that abstained on half the questions (OpenAI, “Why language models hallucinate”).
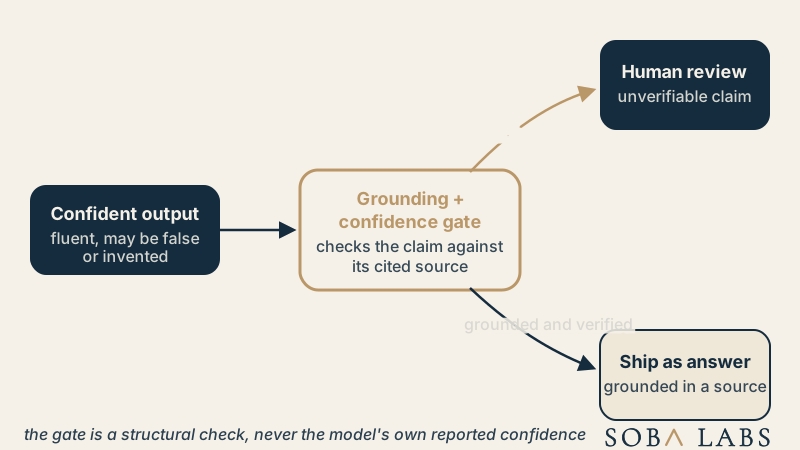
Hallucination is not a party trick to marvel at. It is a production risk you gate, measure, and design around, the same discipline any regulated process applies to human error.
Where does hallucination actually show up in a business system?
Anywhere a model is asked a question its sources cannot actually answer: a policy detail that was never written down, a number outside the retrieved documents, a customer history the system was not given. The model does not know the difference between an answer it retrieved and an answer it invented, so a support agent quoting a refund policy that does not exist, or a research assistant citing a study that was never published, are the same underlying failure wearing different clothes. In sales the same failure is a wrong price or a stock level nobody checked, which is why the offer assistant in our Gamrat case study links every quoted price to an approved source and flags the rest for a salesperson.
Why does grounding reduce it without solving it?
RAG helps because it forces the model to answer from retrieved text instead of pure memory, and citations let a person check the claim against its source. It is not a fix on its own: retrieval can return the wrong passage, the model can misread a correct passage, or it can blend a retrieved fact with something it half-remembers from training. Grounding lowers the rate; it does not lower it to zero, which is why a hallucination strategy needs a second layer beyond retrieval.
What actually catches a hallucination before a customer does?
Not asking the model to rate its own confidence: that self-report is poorly calibrated and clusters near certain even when wrong, a finding detailed in why self-reported confidence is not a reliable signal. The controls that hold up are structural: guardrails that block a class of unverifiable claims outright, a human approval gate on anything consequential, and citation checks that verify a claim actually appears in the source it names, not just that a source was attached.
What should a company actually do about it?
Decide the acceptable error rate per workflow before building, the same way a fraud team sets a tolerance rather than aiming for theoretical zero. A drafting tool that a person reviews can tolerate a higher rate than a system that emails a customer unattended. Our AI readiness assessment scores exactly this tradeoff for one workflow: whether the data and review points exist to run an LLM-based system at an error rate the business can actually live with.